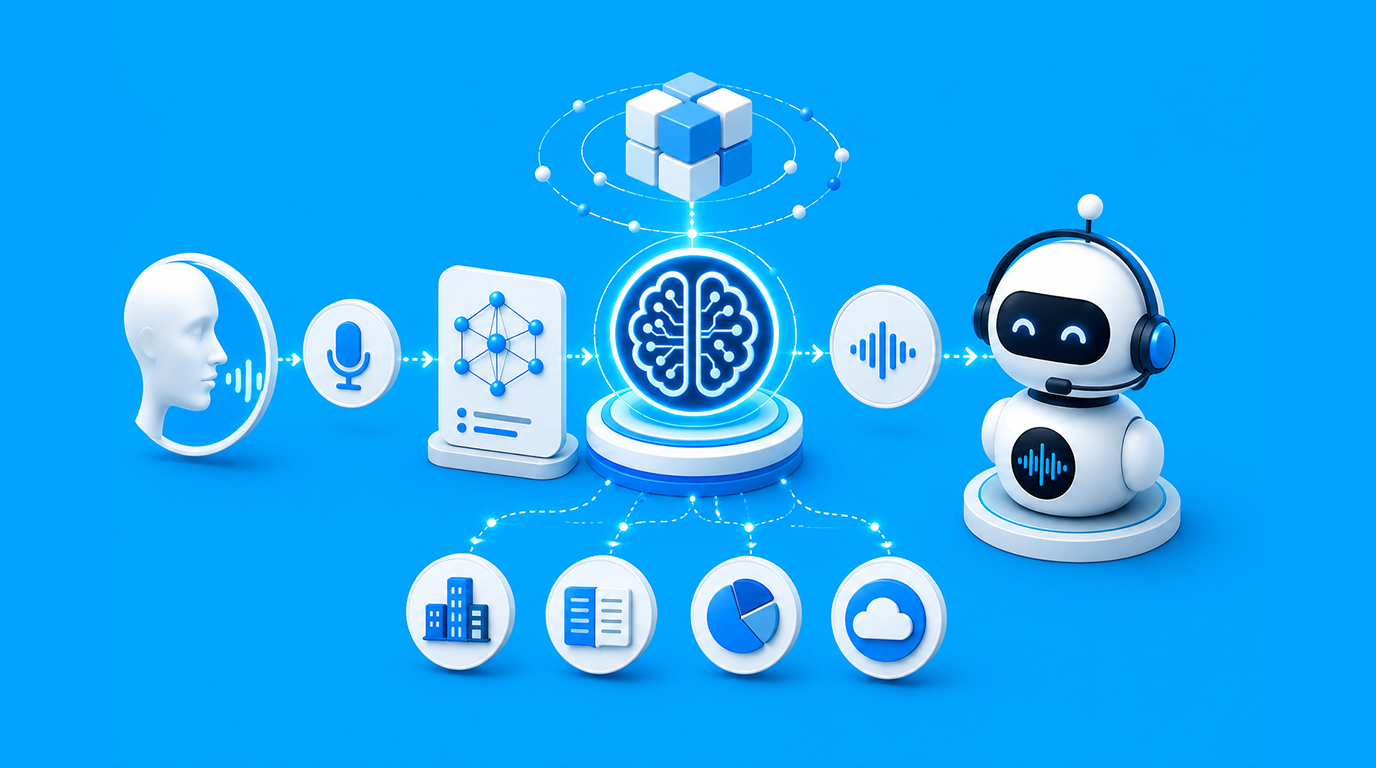
ജനറൽ പർപ്പസ് ഫൌണ്ടേഷൻ മോഡലുകളിൽ നിർമ്മിച്ച കോൾ സെന്റർ വോയ്സ് ബോട്ടുകൾ പ്രവർത്തനപരമായി വിശ്വസനീയമല്ലാത്ത നിരക്കിൽ ഡൊമെയ്ൻ നിബന്ധനകളെ തെറ്റായി തിരിച്ചറിയുന്നു. ബിഎഫ്എസ്ഐ വിന്യാസങ്ങളിൽ, "ഇഎംഐ" യെ "ആർമി" എന്ന് മിസ്സർ ചെയ്യുന്ന അല്ലെങ്കിൽ "കെവൈസി പെൻഡിംഗ്" എന്ന് വ്യാഖ്യാനിക്കുന്ന ഒരു ബോട്ട് ഉപഭോക്താവിനെ നിരാശപ്പെടുത്തുക മാത്രമല്ല, അത് ഒരു കംപ്ലയിൻസ് എക്സ്പോഷർ സൃഷ്ടിക്കുകയും ചെയ്യുന്നു. ഫൌണ്ടേഷൻ മോഡലുകൾക്ക് എന്തുചെയ്യാൻ കഴിയും, എന്റർപ്രൈസ് വോയ്സ് എ. ഐ. ക്ക് യഥാർത്ഥത്തിൽ ആവശ്യമുള്ളത് തമ്മിലുള്ള വിടവ് ഒരു പ്രോംപ്റ്റ് എഞ്ചിനീയറിംഗ് പ്രശ്നമല്ല. ഇത് ഒരു വാസ്തുവിദ്യാ പ്രശ്നമാണ്.
ആ വിടവ് നികത്താൻ ഡൊമെയ്ൻ-നിർദ്ദിഷ്ട ഭാഷാ മോഡലുകൾ നിലവിലുണ്ട്. ഈ പോസ്റ്റിന്റെ അവസാനത്തോടെ, ഡൊമെയ്ൻ ഭാഷാ മോഡലുകൾ എങ്ങനെ പെർഫോമൻസ് പ്രൊഫൈൽ മാറ്റുന്നുവെന്ന് നിങ്ങൾക്ക് കൃത്യമായി മനസ്സിലാകും സംഭാഷണ AI വോയ്സ് ബോട്ടുകൾ എന്തുകൊണ്ടാണ് നിയന്ത്രിത വ്യവസായങ്ങൾക്ക് അത് പ്രധാനമായിരിക്കുന്നത്, അത് പ്രവർത്തിക്കുമ്പോൾ വാസ്തുവിദ്യ എങ്ങനെയായിരിക്കും.
കോൺവെർസേഷണൽ എഐ വോയ്സ് ബോട്ടുകളിൽ എന്താണ് ജനറൽ ഫൌണ്ടേഷൻ മോഡലുകൾക്ക് തെറ്റ് സംഭവിക്കുന്നത്
ഫൌണ്ടേഷൻ മോഡലുകൾക്ക് ബ്രോഡ് ഇൻറർനെറ്റ് കോർപ്പറയിൽ പരിശീലനം നൽകുന്നു. പൊതുവായ ഭാഷ മനസ്സിലാക്കുന്നതിൽ അവർ മികച്ചവരാണ്, എന്നാൽ ഡൊമെയ്ൻ അവ്യക്തതയിൽ ദുർബലരാണ്, പ്രത്യേകിച്ച് എഎസ്ആർ (ഓട്ടോമാറ്റിക് സ്പീച്ച് റെക്കഗ്നിഷൻ) ആദ്യം പരിവർത്തനം ചെയ്യുന്ന ശബ്ദ സന്ദർഭങ്ങളിൽ ടെക്സ്റ്റിലേക്കുള്ള പ്രസംഗം ഏതെങ്കിലും ഭാഷാ പ്രോസസ്സിംഗ് നടക്കുന്നതിന് മുമ്പ്.
വോയ്സ് എഐയിൽ രണ്ട് പരാജയ പോയിന്റുകൾ സംയുക്തംഃ
സാധാരണ വാക്കുകളുമായുള്ള ശബ്ദപരമായ സാമ്യം കാരണം എഎസ്ആർ ലെയർ ഒരു ഡൊമെയ്ൻ പദം തെറ്റായി ട്രാൻസ്ക്രൈബ് ചെയ്തേക്കാം.
പിശക് വീണ്ടെടുക്കാൻ കഴിയുമ്പോൾ പോലും, ഡൌൺസ്ട്രീം ലാംഗ്വേജ് മോഡലിന് സന്ദർഭത്തിൽ നിന്ന് ശരിയാക്കാനുള്ള സ്കീമ ഇല്ലായിരിക്കാം.
ഒരു ബാങ്കിംഗ് ഐവിആറിൽ, "എൻഎസിഎച്ച് മാൻഡേറ്റ്", "എൻഎടിസിഎച്ച് മാൻഡേറ്റ്" എന്നിവ ഒരു ജനറിക് എഎസ്ആർ സംവിധാനത്തിന് സമാനമാണ്. ബാങ്കിംഗ് പദാവലിയിൽ പരിശീലനം ലഭിച്ച ഒരു ഡൊമെയ്ൻ ഭാഷാ മോഡൽ സന്ദർഭത്തിൽ നിന്ന് ഇത് പരിഹരിക്കുന്നു. ഒരു ജനറിക് അല്ല.
കോൾ സെന്റർ വോയ്സ് ബോട്ട് വിന്യാസങ്ങളുടെ ഫലം ഉയർന്ന തെറ്റായ തിരിച്ചറിയൽ നിരക്കുകൾ, വർദ്ധിച്ച ഏജന്റ് എസ്കലേഷൻ വോള്യങ്ങൾ, സ്വയം സേവന ടച്ച് പോയിന്റുകളിൽ ഉപഭോക്തൃ ഉപേക്ഷിക്കൽ എന്നിവയാണ്. എന്റർപ്രൈസസ് സാധാരണയായി ഇത് മോഡൽ ആർക്കിടെക്ചറിന് ആട്രിബ്യൂട്ട് ചെയ്യുന്നില്ല, അതായത് സിഎക്സ് ടീമുകൾ രോഗലക്ഷണ-ലെവൽ പരിഹാരങ്ങൾ പിന്തുടരുമ്പോൾ മൂലകാരണം പരിഹരിക്കപ്പെടാതെ പോകുന്നു.
സംഭാഷണ AI-നായി ഡൊമെയ്ൻ ഭാഷാ മോഡലുകൾ എങ്ങനെ നിർമ്മിക്കുന്നു
ഒരു ഇൻഡസ്ട്രി വെർട്ടിക്കലിന് പ്രത്യേകമായി ക്യൂറേറ്റഡ് ഡാറ്റയിൽ പരിശീലനം ലഭിച്ച ചെറുതും മികച്ചതുമായ മോഡലാണ് ഡൊമെയ്ൻ ലാംഗ്വേജ് മോഡൽ. ബിഎഫ്എസ്ഐയിൽ, അതായത് ലോൺ ഡോക്യുമെന്റേഷൻ, റെഗുലേറ്ററി സർക്കുലറുകൾ, ഉൽപ്പന്ന വെളിപ്പെടുത്തൽ പ്രസ്താവനകൾ, കളക്ഷൻ സ്ക്രിപ്റ്റുകൾ, പരാതി പരിഹാര കത്തിടപാടുകൾ. ടെർമിനോളജി, വാക്യഘടന പാറ്റേണുകൾ, നിർണായകമായി, ഉപഭോക്താക്കൾ ആ ഡൊമെയ്നിലെ പ്രശ്നങ്ങൾ യഥാർത്ഥത്തിൽ എങ്ങനെ പ്രകടിപ്പിക്കുന്നുവെന്ന് നിർവചിക്കുന്ന ഉദ്ദേശ്യ വർഗ്ഗീകരണം എന്നിവ മോഡൽ പഠിക്കുന്നു.
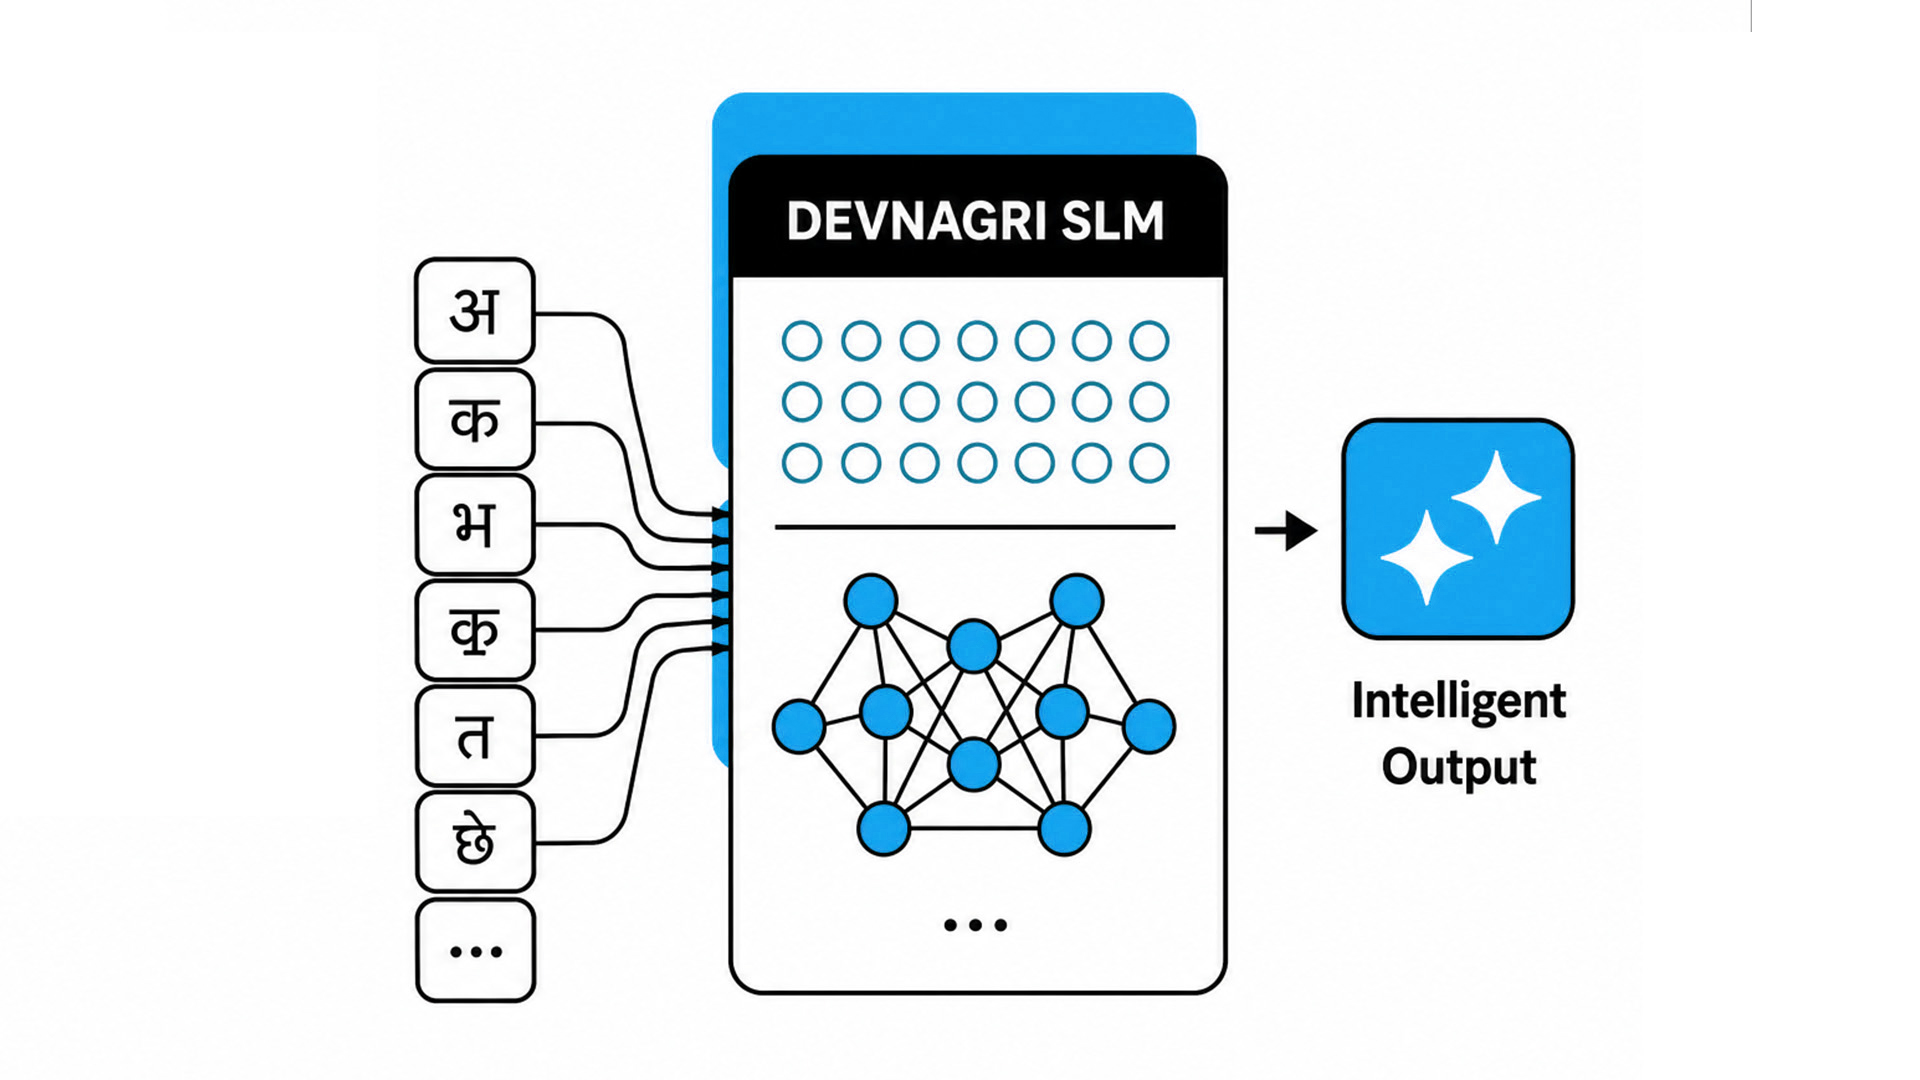
ബിഎഫ്എസ്ഐയ്ക്കുള്ള ദേവനാഗ്രിയുടെ ഡൊമെയ്ൻ SLMs ഇംഗ്ലീഷ് സാമ്പത്തിക വാചകത്തിൽ മാത്രമല്ല, പ്രാദേശിക ഭാഷാഭേദങ്ങൾ ഉൾപ്പെടെ ഇന്ത്യൻ ഭാഷകളിൽ ഉടനീളം പരിശീലിപ്പിച്ചിരിക്കുന്നു, അവിടെ സാമ്പത്തിക പദാവലി പലപ്പോഴും ഇംഗ്ലീഷിനും പ്രാദേശിക ഭാഷയ്ക്കും ഇടയിലുള്ള വാക്യങ്ങൾക്കിടയിൽ കോഡ്-സ്വിച്ച് ചെയ്യുന്നു. മേവാരി-ഇൻഫ്ലക്റ്റഡ് ഹിന്ദി സംസാരിക്കുന്ന രാജസ്ഥാനിലെ ഒരു ഉപഭോക്താവിനെ കൈകാര്യം ചെയ്യുന്ന ഒരു കളക്ഷൻ ബോട്ടിന് കോഡ്-സ്വിച്ച് ചെയ്ത ഉദ്ദേശ്യം അംഗീകരിക്കുന്ന ഒരു ഭാഷാ മോഡൽ ആവശ്യമാണ്, അല്ലാതെ ഉച്ചാരണത്തെ അവ്യക്തമായി ഫ്ലാഗ് ചെയ്യുന്ന ഒരു പൊതുവായ മോഡൽ അല്ല.
ഈ സ്പെഷ്യലൈസേഷൻ അർത്ഥമാക്കുന്നത് ചെറിയ മോഡലുകൾ ഡൊമെയ്ൻ-നിർദ്ദിഷ്ട വോയ്സ് ടാസ്ക്കുകളിൽ വളരെ വലിയ ജനറൽ പർപ്പസ് മോഡലുകളെ മറികടക്കുന്നു, കുറഞ്ഞ ലേറ്റൻസിയും കുറഞ്ഞ കമ്പ്യൂട്ട് ചെലവും.
സംഭാഷണ AI ശബ്ദ കൃത്യതയിൽ എഎസ്ആർ ഗുണനിലവാരത്തിന്റെ പങ്ക്
ഒരു ഡൊമെയ്ൻ ലാംഗ്വേജ് മോഡലിന് അതിന്റെ ജോലി ചെയ്യാൻ കഴിയുന്നതിനുമുമ്പ്, ഒരു എഎസ്ആർ എഞ്ചിൻ വിളിച്ചയാൾ പറഞ്ഞതിന്റെ കൃത്യമായ ട്രാൻസ്ക്രിപ്റ്റ് നിർമ്മിക്കണം. പ്രാഥമികമായി ഇംഗ്ലീഷിലോ സ്റ്റാൻഡേർഡ് ഹിന്ദിയിലോ പരിശീലനം ലഭിച്ച ജെനറിക് എഎസ്ആർ സംവിധാനങ്ങൾ പ്രാദേശിക ഇന്ത്യൻ ഭാഷാ ഇൻപുട്ടുകളിൽ, പ്രത്യേകിച്ച് പശ്ചാത്തല ശബ്ദം, ഭാഷാ വ്യതിയാനം, മിക്സഡ്-സ്ക്രിപ്റ്റ് ഉച്ചാരണം എന്നിവയുള്ള ടെലിഫോണി-ഗ്രേഡ് ഓഡിയോയിൽ മോശം പ്രകടനം കാഴ്ചവയ്ക്കുന്നു.
എന്റർപ്രൈസ്-ഗ്രേഡ് കൺവർസേഷണൽ എഐ വോയ്സ് ഇൻഫ്രാസ്ട്രക്ചർ ഡൊമെയ്ൻ ട്യൂൺ ചെയ്ത എഎസ്ആർ ലെയറിനെ ഡൊമെയ്ൻ ഭാഷാ മോഡലുമായി സംയോജിപ്പിക്കണം. ഒന്നില്ലാതെ മറ്റൊന്ന് പൊട്ടുന്ന ഒരു സംവിധാനം സൃഷ്ടിക്കുന്നുഃ
ഒരു കുറഞ്ഞ ഭാഷാ മോഡൽ നൽകുന്ന കൃത്യമായ സംസാര തിരിച്ചറിയൽ ബോട്ടിന് ശരിയായി വ്യാഖ്യാനിക്കാൻ കഴിയാത്ത കൃത്യമായ ട്രാൻസ്ക്രിപ്ഷനുകൾ നിങ്ങൾക്ക് നൽകുന്നു.
ദുർബലമായ എഎസ്ആറിന്റെ താഴേക്കുള്ള ഒരു ശക്തമായ ഭാഷാ മോഡലിന് തുടക്കം മുതൽ കേടായ ഇൻപുട്ട് ലഭിക്കുന്നു.
AI-അസിസ്റ്റഡ് പബ്ലിക് സർവീസസിനെക്കുറിച്ചുള്ള DEITY റിപ്പോർട്ട് ഇന്ത്യൻ ഭാഷകളിലെ എഎസ്ആർ കൃത്യത ഒരു പ്രാഥമിക വിന്യാസ തടസ്സമായി ഫ്ലാഗ് ചെയ്തു, മോഡൽ ഇന്റലിജൻസ് അല്ല. കോൾ സെന്റർ വോയ്സ് ബോട്ട് സൊല്യൂഷനുകൾ വിലയിരുത്തുന്ന ഓർഗനൈസേഷനുകൾ ടാർഗെറ്റ് ഭാഷകളിലുടനീളമുള്ള എഎസ്ആർ ഗുണനിലവാരത്തെ നെഗോഷ്യബിൾ അല്ലാത്ത ആദ്യ മാനദണ്ഡമായി കണക്കാക്കണം.
എന്തുകൊണ്ട് സംഭാഷണ AI ബോട്ടുകൾക്ക് ഒരു കൾച്ചറൽ ഇന്റലിജൻസ് ലെയർ ആവശ്യമാണ്
ഭാഷാ ഗ്രാഹ്യം മാത്രം ഉചിതമായ ശബ്ദ AI പെരുമാറ്റം സൃഷ്ടിക്കുന്നില്ല. രണ്ട് സംഭാഷണങ്ങളും നഷ്ടമായ ഇഎംഐയെക്കുറിച്ചാണെങ്കിൽപ്പോലും മഹാരാഷ്ട്രയിലെ ഒരു കളക്ഷൻ ബോട്ടും തമിഴ്നാട്ടിലെ ഒരു കളക്ഷൻ ബോട്ടും ഒരേ സാംസ്കാരിക പശ്ചാത്തലത്തിൽ പ്രവർത്തിക്കുന്നില്ല. ടോൺ, ഔപചാരികത രജിസ്റ്റർ, സ്വീകാര്യമായ നിശ്ചയദാർഢ്യ നിലവാരം, സ്വയം സേവനത്തിൽ നിന്ന് മനുഷ്യ ഏജന്റിലേക്ക് വളരുന്നതിനുള്ള ശരിയായ നിമിഷം എന്നിവയെല്ലാം പ്രദേശത്തിനനുസരിച്ച് വ്യത്യാസപ്പെടുന്നു.
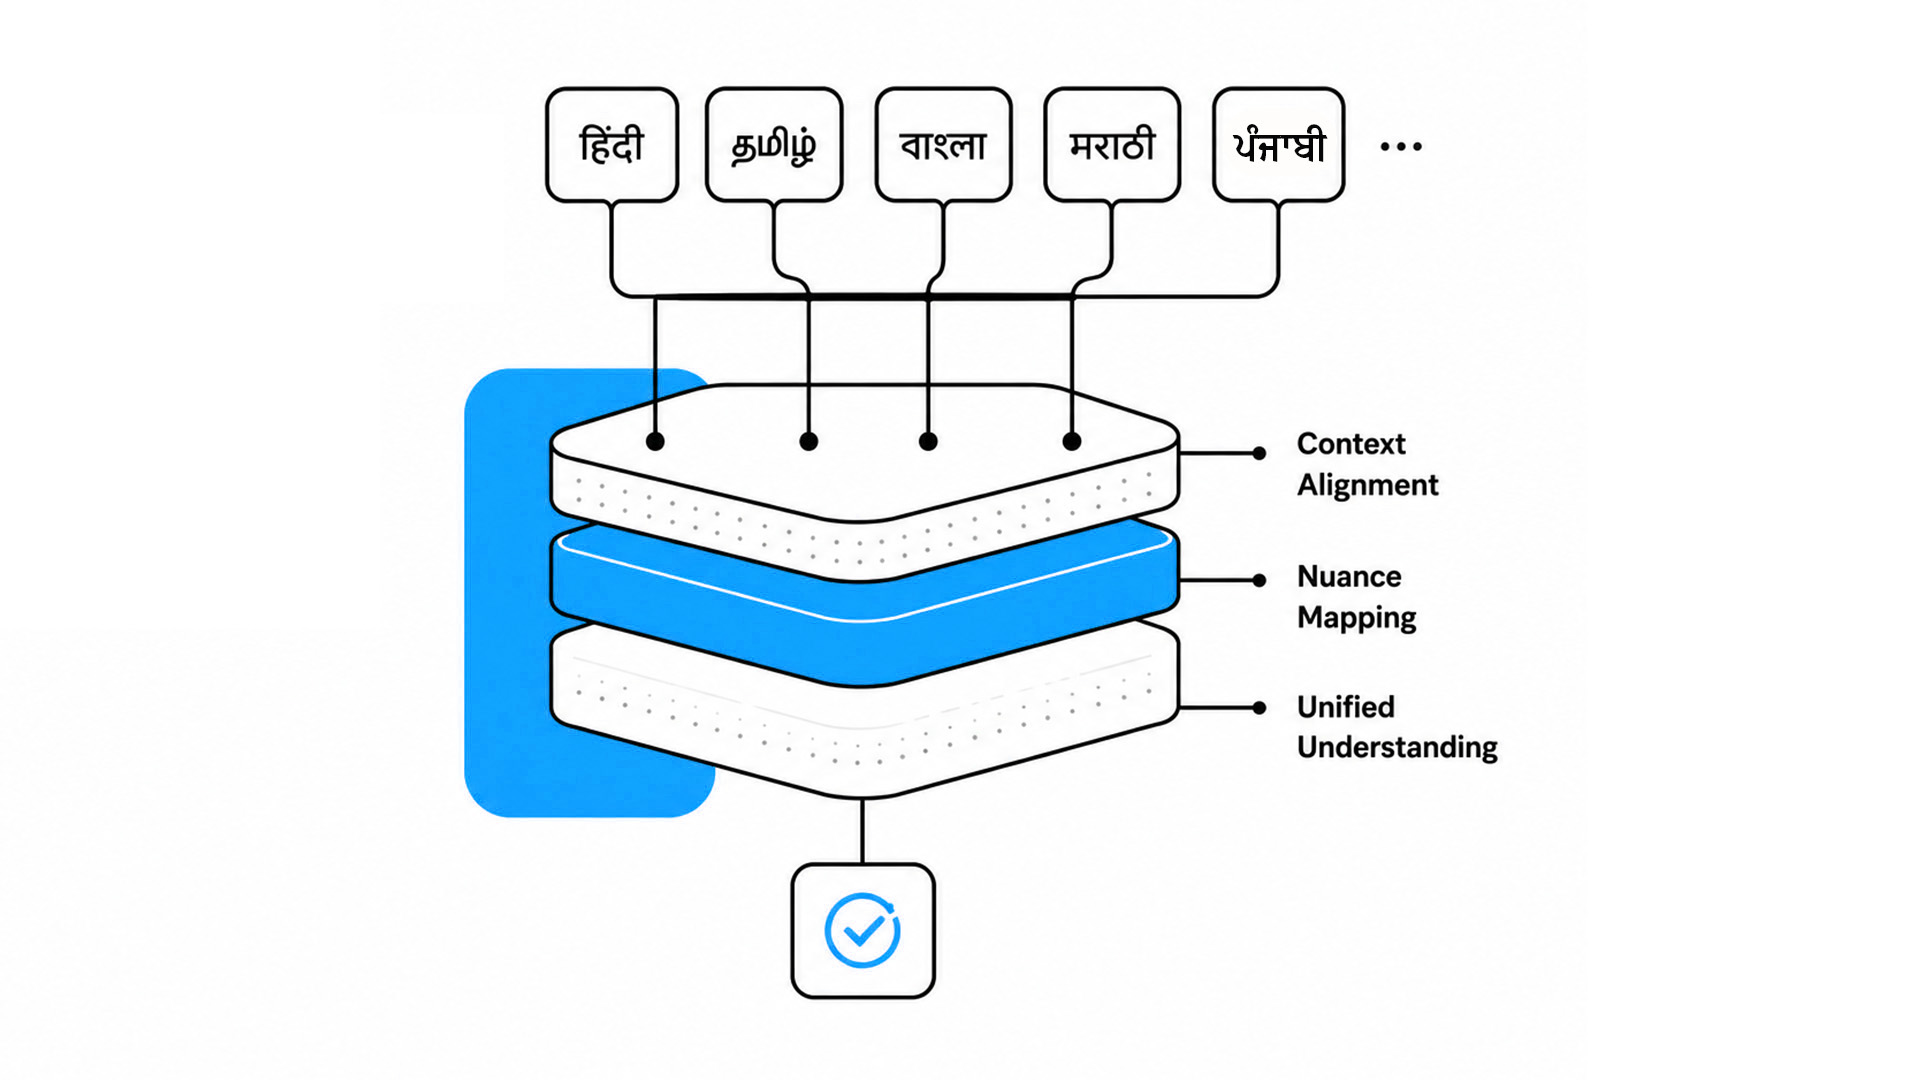
A cultural intelligence layer sits above the domain language model and governs how outputs are constructed. In Devnagri's architecture, this includes a tone engine that calibrates output between soft, firm, and reminder modes based on prior interaction history, account status, and regional norms. The आप versus तुम distinction in Hindi-language voice output is not a stylistic preference; in a collections context, it affects right-party contact rates and customer sentiment at a statistically meaningful level.
ഇത് ഒരു വിവർത്തന പ്രശ്നമായി കണക്കാക്കുന്ന ഓർഗനൈസേഷനുകൾ ശരിയായ ഭാഷ സംസാരിക്കുന്ന ബോട്ടുകൾ വിന്യസിക്കുന്നു, എന്നാൽ തെറ്റായ സന്ദർഭം. ഉപഭോക്തൃ വിച്ഛേദനം, എസ്കലേഷൻ വോള്യങ്ങൾ എന്നിവയാണ് ഫലം, അത് വോയ്സ് എഐയുടെ ചെലവ് കേസിനെ പൂർണ്ണമായും നിഷേധിക്കുന്നു.
കോൾ സെന്റർ വോയ്സ് ബോട്ട് ആർക്കിടെക്ചർ: എന്റർപ്രൈസ് ഡിപ്ലോയ്മെന്റ് യഥാർത്ഥത്തിൽ എന്താണ് ആവശ്യപ്പെടുന്നത്
A production-grade call center voice bot is not a single model. It is an orchestrated stack, and each component must be governed with every handoff logged:
- Telephony integration, inbound call routing and IVR trigger
- ASR layer, domain-tuned, language-specific speech-to-text
- Domain language model, intent classification and entity extraction
- Intent router, self-service resolution or human escalation logic
- TTS layer, natural, tone-controlled voice output in the caller's language
- CRM / Core Banking integration, real-time account context pulled per interaction
- Audit log, immutable record of transcript, model version, classification, and outcome
For regulated sectors, the audit layer is not optional. RBI's Digital Lending Guidelines require that AI-mediated customer interactions maintain full traceability. A voice bot that cannot produce an immutable transcript of every call is not compliant regardless of how well it handles calls.
Devnagri's conversational AI infrastructure includes zero-data-retention defaults with configurable audit log policies, VPC and on-premises deployment options for organizations with data residency requirements, and integration pathways into core banking and CRM systems.
ആശയവിനിമയ AI വോയ്സ് ബോട്ടുകൾ യഥാർത്ഥത്തിൽ മെച്ചപ്പെടുത്തുന്നത് എന്താണെന്ന് അളക്കുന്നു
Voice bots are frequently measured on the wrong metrics: containment rate and average handle time at the call center level. Those metrics tell you whether the bot handled the interaction, not whether it handled it well. A bot that resolves 80% of calls through misclassified outcomes inflates containment while degrading customer trust.
The right measurement frame for conversational AI voice bots in enterprise deployments covers:
First-contact resolution rate, by language segment, not aggregate
Post-call NPS, broken down by language and intent category
Escalation rate per intent, flags model failure points at the use-case level
Regulatory compliance incident rate, per thousand interactions, not per quarter
Organizations that track these metrics see domain language models outperform generic alternatives by margins that justify the infrastructure investment. Devnagri's collections voice bot deployments in BFSI have produced 20-30% improvement in collections response rates, driven primarily by language-appropriate engagement rather than scripting changes.
സംഭാഷണ AI വോയ്സ് ഇൻഫ്രാസ്ട്രക്ചർ ഭാഷകളിലുടനീളം എങ്ങനെ സ്കെയിൽ ചെയ്യുന്നു
India's linguistic diversity is not a UX consideration for enterprise voice AI; it is an infrastructure requirement. A bank with customers across 18 states is operating across a minimum of eight primary languages and dozens of regional dialects. A call center voice bot that handles Hindi and English but not Tamil, Telugu, Marathi, or Bengali is not a language AI deployment, it is a partial one.
Scaling conversational AI voice coverage requires domain language models trained per language, not a single model with language-switching logic patched on. Each language domain model must be calibrated for ASR accuracy in that language, intent taxonomy in that language, and Text to speech (TTS) voice quality in that language. Organizations that assess this architecture before procurement avoid the costly rebuild that follows a narrow-language deployment that fails to serve the actual customer base.
ഉപസംഹാരം
Domain language models are not an enhancement to conversational AI voice bots, they are the architecture decision that determines whether a voice bot deployment performs or fails in regulated enterprise environments. Generic foundation models cannot supply the domain context, regional language depth, or governance posture that BFSI and similarly regulated sectors require. The organizations building durable voice AI capabilities are treating this as an infrastructure decision, not a software selection.
If your organization is evaluating call center voice bot options for regional language deployments, book a platform walkthrough with Devnagri to review the domain SLM architecture and live deployment examples from BFSI.
A voice bot that cannot understand your customer is not an AI problem, it is a data and architecture problem that no amount of prompting will fix.